LiquidEdge AI PODLE-44
Single-Rack · Edge
 44 kW IT
- 64× RTX 5090 · 32× H100/H200 · 24× B200
- Inference · Fine-tuning · Edge AI
Factory-built. Plug-and-play. Live in eight weeks.
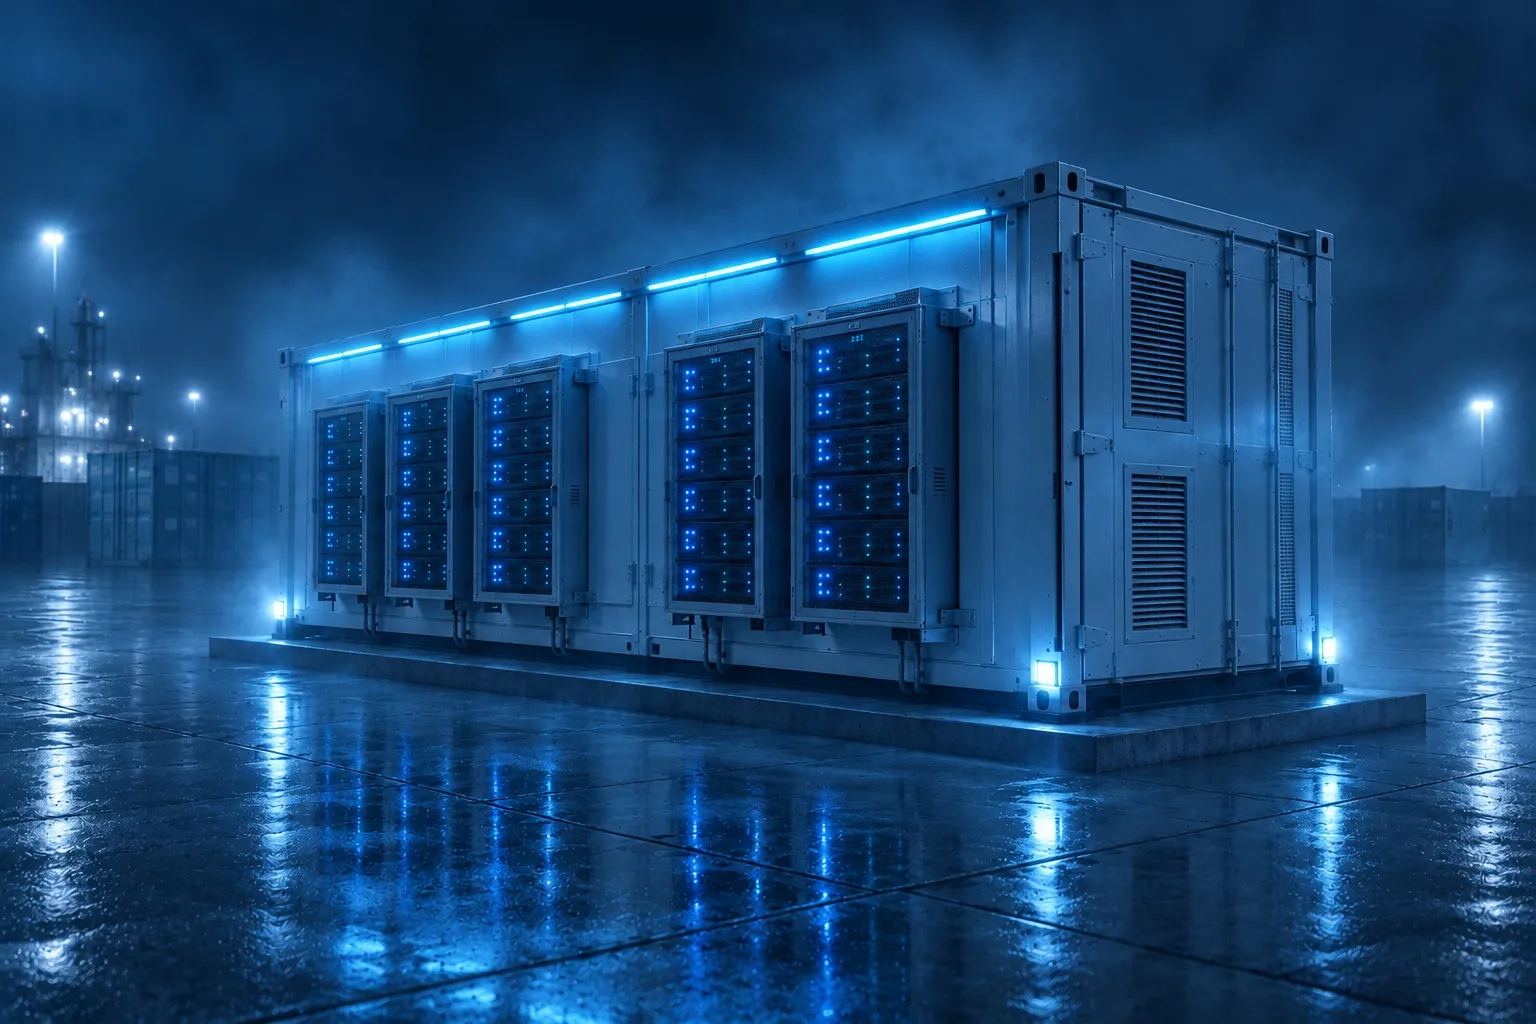
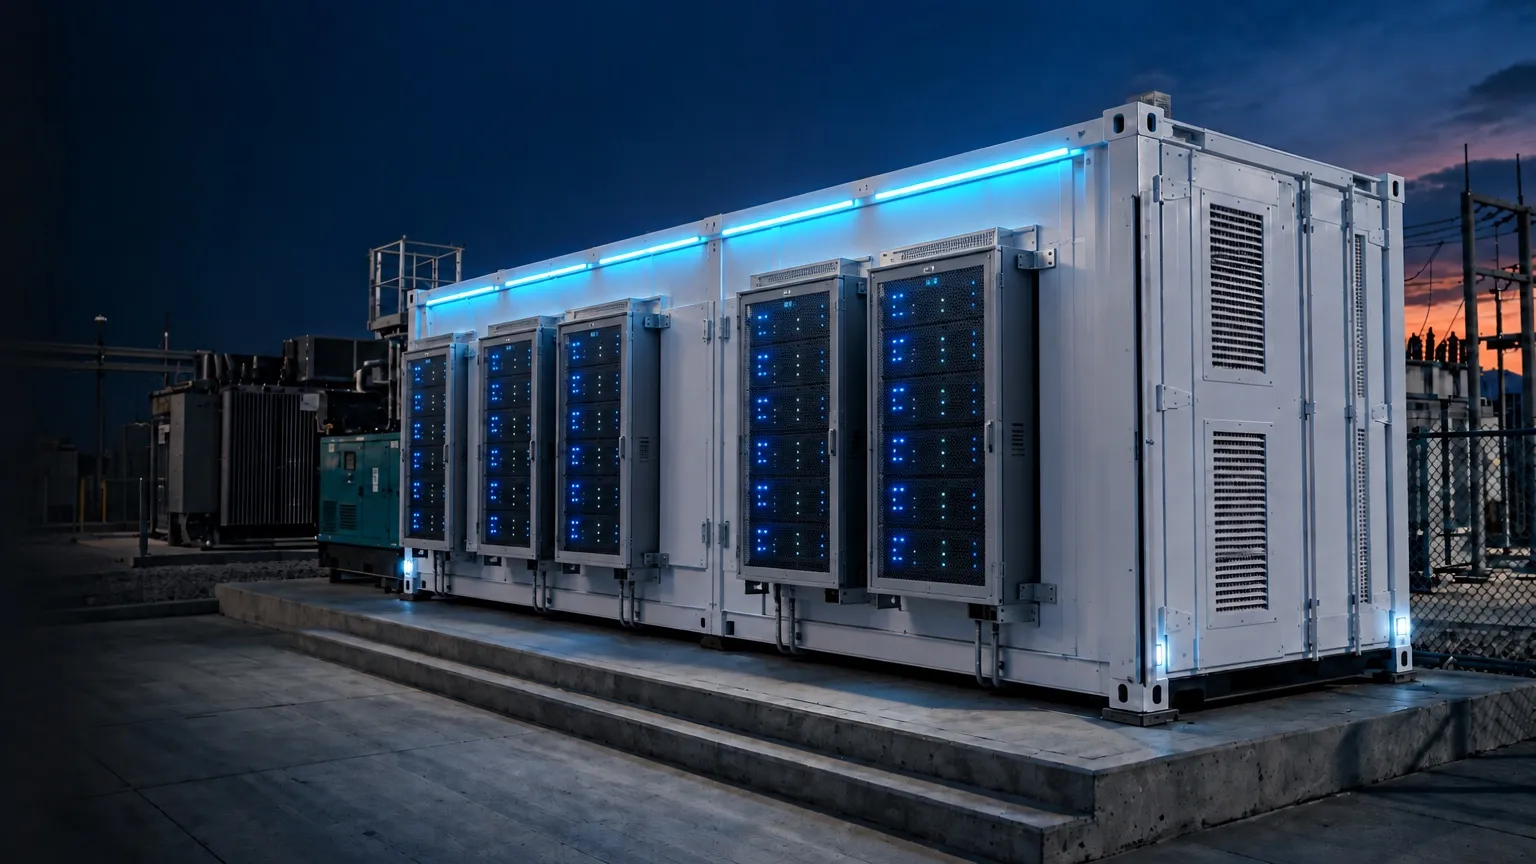
The LiquidEdge AI POD is a complete liquid-cooled AI datacenter inside a 40-ft North American-spec ISO container. It is assembled and tested at the factory, then arrives on site ready to connect, with no civil works and fewer than five crew members needed at installation.
Conventional datacenter builds can take 36 months or more because of grid interconnect queues, permitting and construction. The POD was engineered to remove that bottleneck: wherever power is available, from industrial sites to urban brownfields, it goes from factory to live in about eight weeks. Noviant offers it in partnership with LiquidEdge, backed by its majority owner Aether Compute.
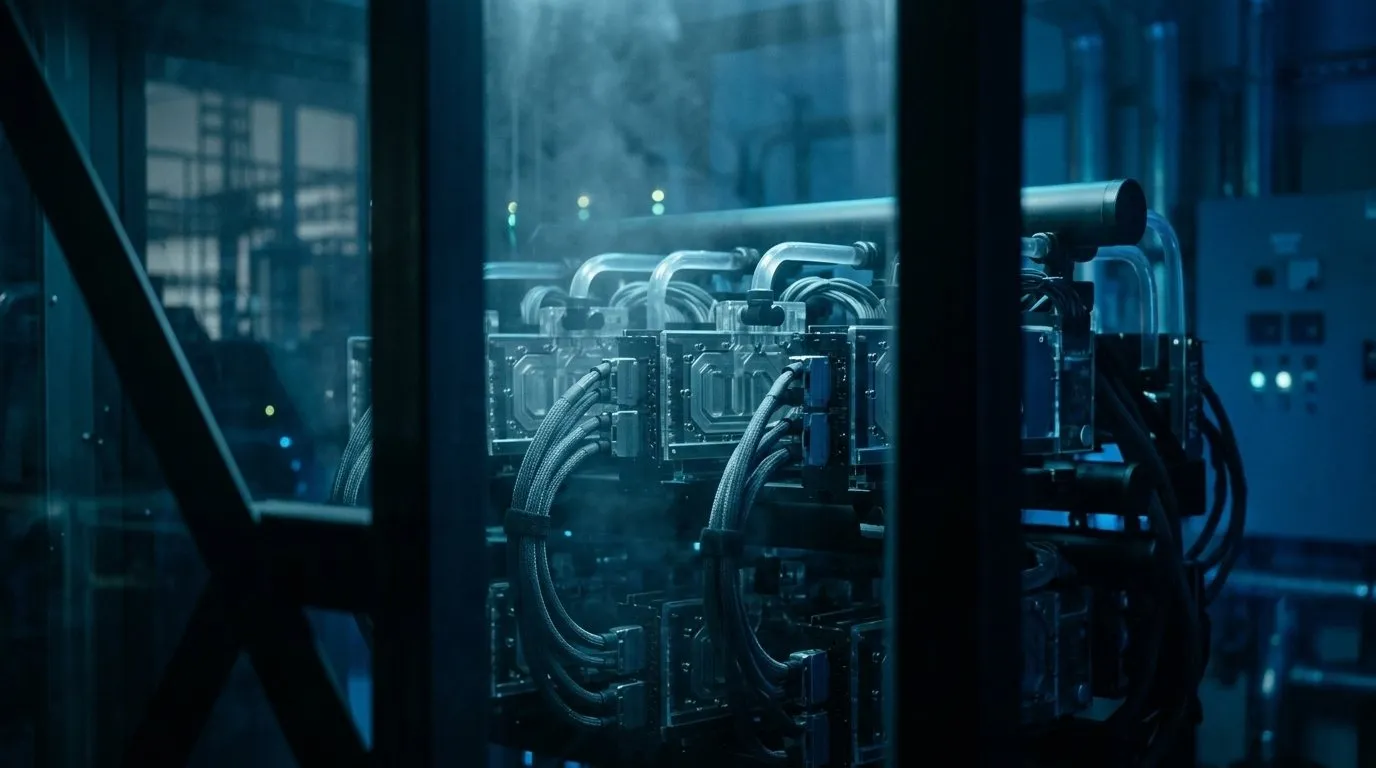
Cold-plate technology captures at least 80% of GPU heat into the coolant loop, for an annualized PUE of 1.15 or better against the 1.50 to 1.70 typical of air-cooled rooms.
LE-44 single rack for edge and inference, LE-88 twin rack for Neocloud and GPU-as-a-Service, LE-200 quad rack for LLM training and hyperscaler bridge capacity.
Configurations for NVIDIA GB200, H100, H200, B200 and RTX 5090, and AMD MI300X.
IP55-rated enclosure operating from -40°C to +50°C, fully relocatable and redeployable.
Designed to UL 891, NEC 2023, NFPA 75/76 and ASHRAE TC 9.9.
More than 4,000 telemetry points per unit, a CFD-validated digital twin for workload simulation, and predictive maintenance that flags hardware degradation 72 hours or more in advance.
Liquid-Cooled AI Datacenter Container
Offered by Noviant with LiquidEdge, backed by its majority owner Aether Compute.
North America compliant: UL 891, NEC 2023, NFPA 75/76, ASHRAE TC 9.9.
Single-Rack · Edge
44 kW IT64× RTX 5090 · 32× H100/H200 · 24× B200Inference · Fine-tuning · Edge AIFlagship Model
Twin-Rack · Mainstream
88 kW IT128× RTX 5090 · 64× H100/H200Neocloud · GPU-as-a-ServiceQuad-Rack · Heavy
200 kW IT1× GB200 NVL72 (72 GPUs) · 256× RTX 5090LLM Training · Hyperscaler BridgeEvery tier is factory-built and live in about 8 weeks, uses direct liquid cooling for a PUE of 1.15 or better, and supports NVIDIA and AMD MI300X GPUs. Offered with LiquidEdge, backed by its majority owner Aether Compute.
We review your power availability, GPU requirements and timeline to choose the right tier.
The POD is assembled and tested at the factory while the site connection is prepared.
It arrives ready to connect; a small crew brings it live, about eight weeks from order.
Noviant supports and monitors the POD, with predictive maintenance from the AIOps platform.
Certified since October 26, 2019; certified to ISO/IEC 27001:2022 since October 26, 2025 (valid through October 25, 2028). Certificate No. 382119.00, issued by DEKRA Certification, Inc., an ANAB-accredited certification body. Scope: Managed services including Cybersecurity, Cloud Solutions, Data Analytics, and Data Infrastructure.
Helping state and city agencies meet their Article 15-A goals for minority and women-owned business participation.
About eight weeks from factory to live. The POD is built and tested at the factory, so on-site work is limited to connecting power, cooling and network.
LE-44 (44 kW) suits inference, fine-tuning and edge AI. LE-88 (88 kW) is designed for Neocloud operators and GPU-as-a-Service. LE-200 (200 kW) supports a full NVIDIA GB200 NVL72 system for large language model training. We size it with you based on workload and available power.
Configurations support NVIDIA GB200, H100, H200, B200 and RTX 5090, as well as AMD MI300X.
PUE compares total facility power with the power used by IT equipment. At 1.15 or better, far less energy goes to cooling than in typical air-cooled rooms at 1.50 to 1.70.
Yes. It is a standard 40-ft ISO container and is fully relocatable and redeployable.